the hard truth about token spend
Monday, Oct 26 · 36 min · about 8 min to read
Theo-brain watched all 36 min
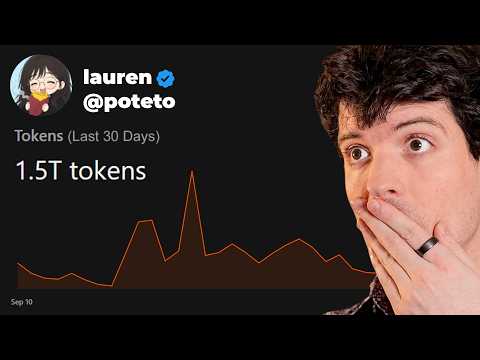
A viral post priced Cursor engineer Lauren's 1.5 trillion tokens at $8 per million. Theo says the math is wrong: the figure lumps together token types priced very differently, his all-in average is 41 cents per million, and he estimates her real spend at roughly $25,000 to $50,000 a month. The bigger lesson is that AI prices are falling fast, roughly 100x in six to eight months.
Briefing is enoughThe briefing covers his numbers and reasoning, so you can skip the video unless you want to hear him make the case himself.
Tap any time to jump the video there.
Key takeaways
The 1.5 trillion figure lumps four token types together, and they are priced very differently. 'Cache reads' are context the model has already seen, billed at a steep discount. On Opus they cost 20 cents per million instead of $5. Theo's all-in average is 41 cents per million, about 20x below the post's $8 assumption.
model, is $8 per mil. What do you think my number per mil is? Spoiler, it's 41 cents. He's off by 20x. He is literally opening with a number that is an order
egregious is because cash read on Opus isn't the usual $5. It's 20 cents. And despite that, half my cost is cash read, a little less than half, but around half is cash read, half is cash write, and the input and output tokens, the ones he is basing the price on, make up less than 8% of my total spent. He averaged
AI is getting cheaper faster. A given level of intelligence used to drop about 10x in price per year. Theo now sees roughly 100x drops in six to eight months.
you see where we're going here? Not only is intelligence getting cheaper, it's getting cheaper faster. It used to take a year for a 10x decrease. Now it takes 6 to 8 months for a 100x decrease. And this is where I
A task like fixing a bug can cost the same as a year ago. That is because the agent now does the whole job. Before, you found the bug, opened the file, had the model edit it, and reran the app yourself. Now Theo hands the model a screenshot and says 'fix'.
worked. The same task now is me handing a screenshot of the bug to the model and saying fix. And yeah, in that case, the task didn't get cheaper, but I'm not doing the [ __ ] work anymore. Sure, closing that ticket on Jira costs the same amount, but I didn't do the work this time. If I was to keep using Cursor
Theo estimates Lauren's real spend at roughly $25,000 to $50,000 a month. For that she files thousands of pull requests (proposed code changes) a month across Cursor and Grokbot. He says judging her by 'dollars in, software out' ignores that her spend also buys research and marketing.
She's filing thousands of PR's a month, landing endless changes across all of these products, fixing things constantly. And it's only probably costing 25 to like worst case 50 grand a month based on reasonable estimates of what her token spend would be.
engineers. Measuring her work as dollars in software out is reductive and wrong. Her spend should be looked at as a combination of product and eng, research, FTE work with P stack, marketing, and like product research and
Two skills here are new to you.
GLM-5.3 Flash as a cheap workhorse model
- What it is
- A low-cost model from GLM. Theo says it matches or beats last year's top model, GPT-5 High, on benchmarks.
- Why Theo cares
- He would pick it over any model from last year. It is pleasant to work with and good at long agentic tasks: you ask it to do something and it does it. In benchmark runs it was 29x cheaper than GPT-5.
- How to try it
- Ask your coding agent to run a routine, multi-step task with GLM-5.3 Flash.
- Compare its result and cost against your usual model on the same task.
I would never choose GPT-5 or O1 or any model released last year over GLM-53 Flash because 53 Flash is genuinely really pleasant to work with. It's good at long-running agentic tasks. You ask it to do a thing and it does it. You ask it to do another thing and it
out to 20x cheaper. I then point out that GLM-53 flash is more pleasant to use and is 29 times cheaper than GPT-5 in bench runs. You're getting better
Have an AI fact-check viral numbers New
- What it is
- When a post shares cost figures that seem off, screenshot it and ask Claude or Codex to check the math.
- Why Theo cares
- He says even the dumbest current models could explain why the numbers in posts like this make no sense.
- How to try it
- Screenshot the post with the numbers.
- Give it to Claude or Codex and ask it to verify the calculations and assumptions.
when you see people sharing numbers that are obviously wrong, or maybe just seem like they might not be right, maybe just screenshot the tweet and throw it at Claude or Codex and ask them to verify the numbers, because even the dumbest AI models nowadays could probably explain to you why none of the numbers being shared here make any sense at all. The
Log your own model history for auditing New
- What it is
- Theo keeps a terabyte of his own model usage history in a ClickHouse database (a fast analytics database) on his network.
- Why Theo cares
- It lets him audit real costs and behavior himself instead of trusting claims.
- How to try it
- Ask your coding agent to record every model call, including model, tokens and cost, in a database.
- Review it monthly to see your real cost per task.
work with these models. I have built tons of benchmarks. I am evaluating this stuff obsessively. I have a terabyte of my own history with models in a clickhouse database that I set up on my network, so I can audit all of this. And
Advice
Distrust people who dodge the facts and attack motives instead. Examples: 'you're paid by the labs', 'it's marketing', or 'they're just gaming benchmarks'. Theo says they will say anything other than 'you're right'.
The folks I'm warning you about here are going to do the opposite. They will never engage with the points. They're going to steer around them and say something else, like, "Well, yeah, you're paid by the labs." Or, "Well, yeah, they're doing this for marketing."
Hot takes
26 staff-level engineers with no token budget would be less productive than Lauren alone with unlimited tokens, 'comically so'.
I honestly believe 26 staff level engineers with $0 in tokens would be meaningfully less productive than just Lauren by herself with unlimited tokens. I would argue comically so. He does
If he ran Cursor, he would approve $2-3 million a month for Lauren without a second thought and ask if she wanted more.
His reasoning: She is exploring what happens when you ignore the cost of intelligence, and that $10 million in tokens will cost about $10,000 in a year or two.
much, but even if she legitimately wanted to spend two to three mill a month, if I was the CEO of Cursor, I wouldn't even think twice. I would ask if she wanted more. She's exploring what
intelligence. She's not doing it cuz Cursor expects every company to spend 10 mill a year on tokens. She's doing it because that 10 mill on tokens is going to cost $10,000 in a year or two. And of
People who hate OpenAI and Anthropic should be cheering about cheaper inference, not denying it.
His reasoning: Costs are falling so fast that the labs are losing their margins.
money. No. These things are getting cheaper to the point where the labs are losing their margins fast. If you hate OpenAI and Anthropic, you should be listening to me here. You should be
Don't listen to anything his friend David Cramer (Zeeg) says about AI.
His reasoning: He thinks the way Cramer talks about it is actively harmful, because you can't have a conversation without agreeing on facts.
good friend with David Cramer, and say you should not listen to a thing he says about AI, even though I did a panel with him 2 weeks ago about AI, because I legitimately think the way he talks about these things are actively harmful to the space that we are in. If we cannot talk about the facts, then we
How Theo thought about this
Rather than argue, Theo ran a test. He benchmarked O1, the first reasoning model, against newer models on his Skate Bench, a quiz on naming skateboard tricks. He expected about 10x cheaper per year. Gemini 3 Flash scored higher at 58x lower cost a year later, so he changed his mind.
Higher score, not a tenth the price, almost a hundredth the price. 58x lower costs exactly 1 year later. This is where I realized I was wrong. I thought the number was a pretty consistent 10x. It's not. It's closer to a hundredx year-over-year decrease at a given level of intelligence. And I told my agents to
He checks his own past misses. He once mocked Windsurf for letting models run commands as 'baby beginner mode'. He now admits he didn't see that models would do their work through tools and the terminal.
You can just run the command. I was super wrong on that. I did not see the future where models would use tools and bash to do their work. It seems like
Sign in to mark what you've watched and keep notes.
Have a question about this one? Ask about this video →
Theo Daily is unofficial and not affiliated with Theo or t3.gg. Written by Claude Opus 5.5 from each video's transcript.